
A Practical Guide to Protein Mutation Site Prioritization
Published on October 18, 2026
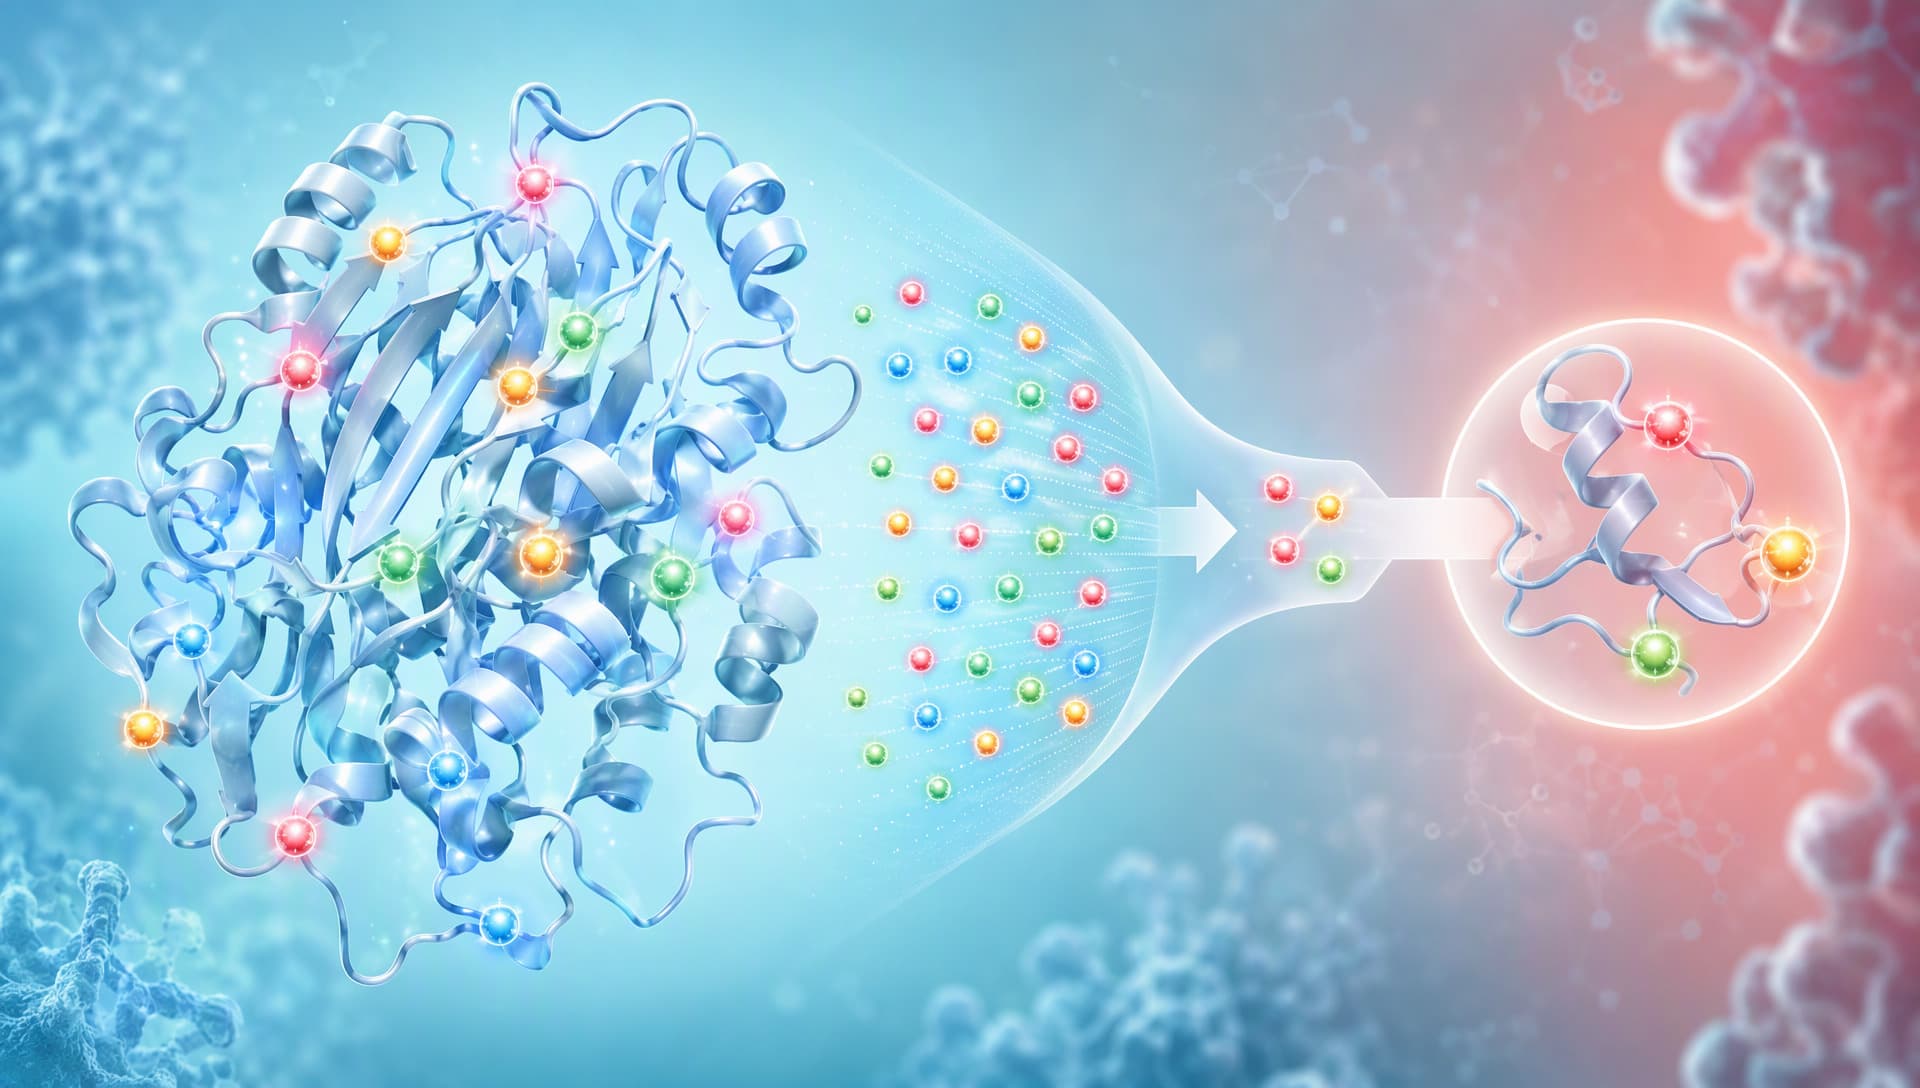
Multiple signals narrow a large mutation space into a focused shortlist
Category: Computational Biology / Protein Engineering / AI-Assisted R&D
When hundreds or thousands of residues could be changed, generating variants is rarely the hardest part. The real challenge is deciding which variants deserve the first experimental batch. A useful protein mutation site prioritization workflow first removes unacceptable functional risks, then compares expected gains, evidence quality, uncertainty, and testability. The outcome should be a shorter list with a clear reason behind every candidate.
Protein mutation site prioritization: a high score is not the same as high experimental value
Evolutionary conservation is informative, but it is not mechanistically unambiguous. A conserved residue may support the folded core, participate directly in catalysis or binding, or connect an allosteric network. Because stability and function both shape sequence evolution, a single conservation or model score may not distinguish a promising engineering position from a residue that should remain untouched.
That is why protein mutation site prioritization benefits from a staged decision. First identify the protein and retrieve relevant prior evidence. Next define a functional no-go zone. Only then evaluate candidates outside that zone for their potential effects on stability, activity, affinity, expression, or another project-specific objective. Candidates with limited evidence do not have to disappear; they should move down the list and carry an explicit uncertainty label.
Large-scale site-saturation studies reinforce this logic. Variant effects can be measured systematically at residue resolution, yet fold stability is only one of several biophysical properties that influence protein function. Computational ranking is therefore most valuable as a way to allocate experimental capacity, not as a replacement for experimental evidence.
A four-layer funnel turns candidates into an executable shortlist
Protect the functional mechanism before optimizing performance
Catalytic residues, ligand-binding pockets, essential interfaces, allosteric networks, and strongly conserved functional positions deserve an explicit risk review. Residues required to preserve the mechanism can be set as a no-go zone. Positions intentionally targeted to alter specificity or binding need a separate, more demanding validation plan rather than the same threshold used for low-risk surface optimization.
MatwingsVenus®(晓鹜®)supports a retrieval-first workflow. Known variants, structures, functional annotations, and experimental baselines are checked before prediction is considered. When authoritative evidence is unavailable and the user approves the next step, VenusX can map functional sites and convert critical residues into design constraints. Retrieved experimental evidence is labeled Measured, computational output is labeled Predicted, and unresolved information remains Unknown. This prevents evidence of different strengths from being blended into one apparently certain answer.

Protect the functional core before evaluating peripheral candidates
Rank against a measurable objective, not a vague promise to improve everything
Before scoring variants, translate the project goal into a measurable priority order. An industrial enzyme may place thermal stability first while requiring activity to remain above an acceptable threshold. A binding protein may prioritize affinity while controlling expression and aggregation risk. When objectives conflict, define a primary objective, hard constraints, and acceptable trade-offs instead of hiding the decision inside a generic “overall performance” score.
At this stage, MatwingsVenus®(晓鹜®)can use VenusREM to evaluate the potential effects of single substitutions on activity, binding, stability, or expression. Structure input may support higher-resolution tasks, but the results remain Predicted. Robust protein mutation site prioritization retains the expected direction of benefit, the source of risk, and the associated uncertainty rather than reporting only a deceptively precise total score.
Reorder candidates by evidence strength and uncertainty
Two variants may both be described as “potentially stabilizing,” yet the claim may come from repeated experiments, curated records, structural interpretation, or model output. Those evidence types should not carry equal confidence. A practical shortlist can separate candidates into three groups: evidence-rich variants ready for an initial test; promising variants that need more structural or experimental context; and high-risk or weakly supported variants that should not consume synthesis capacity yet.
Diversity is another valuable constraint. If every top-ranked mutation sits in the same structural region or uses the same substitution logic, the first batch may simply repeat one hypothesis. Selecting candidates that represent different mechanisms makes each experimental round more informative, even when not every variant succeeds.
Use experimental cost to define the batch boundary
The endpoint is not an attractive ranking chart. It is a batch that can be built, assayed, interpreted, and used to guide the next decision. Construction difficulty, assay throughput, positive thresholds, wild-type and negative controls, and the information value of a failed result all matter. An initial batch can emphasize high-potential, lower-risk, mechanistically diverse single substitutions before moving into combinations.
Once single-mutation results and wet-lab measurements are available, MatwingsVenus®(晓鹜®)can use VenusPrime for multi-mutation modeling. For iterative optimization, ALDE can use experimental data to guide the next round of site selection. The purpose is not to claim a one-shot final answer. It is to ensure that every experiment reduces uncertainty for the following round.

Computational ranking and wet-lab validation form an iterative loop
A reusable scoring logic without fixed universal weights
A protein mutation site prioritization framework can be organized around five questions. Does the candidate avoid unacceptable functional risk? Does it offer a plausible gain against the primary objective? What evidence supports the conclusion? Do sequence, structure, and model signals agree? Can the experiment produce a clear result at a reasonable cost?
There is no universal set of weights. Early discovery may emphasize evidence coverage and mechanistic diversity to avoid premature convergence. Engineering-stage work may place more weight on manufacturability, assay throughput, and target thresholds. Recording each weight change makes promotions and demotions explainable and allows negative results to improve the next cycle.
How MatwingsVenus®(晓鹜®)connects ranking to R&D decisions
A decision-ready output should include the proposed substitution, priority tier, expected benefit, functional risk, evidence label, uncertainty, and recommended validation method. If any of these elements is missing, teams may have to reopen the same debate during experimental planning, reducing the value of computational screening.
MatwingsVenus®(晓鹜®)connects database retrieval, functional-site mapping, single-mutation assessment, combinatorial modeling, and experiment-informed iteration in one task chain. It is designed to turn fragmented outputs into a continuous decision process. Predicted results are not presented as Measured evidence, and compute-intensive tasks require user confirmation before execution. These boundaries make it easier to see what can support a decision now and what remains a hypothesis for validation.
Conclusion: priority is a reasoned next step, not a final verdict
The purpose of protein mutation site prioritization is to test more informative hypotheses with fewer experiments. Protect functional boundaries first, compare expected gains second, calibrate confidence to evidence, and design each batch around cost and mechanistic diversity. For teams building an explainable and traceable protein engineering loop, MatwingsVenus®(晓鹜®)can serve as an entry point connecting retrieval, prediction, combination modeling, and validation planning—so that every prioritized mutation has both a defensible rationale and an executable next step.
